
Playwright Test Agents: Run the Healer Without Losing CI Signal
Playwright Test Agents: run the healer on a branch a person reviews, keep the gating CI job deterministic, and sort each heal diff by cause before it merges.
When a UI change turns the gating CI job red, the Playwright Test Agents healer can propose test edits, but it belongs on a branch where a person reads its diff, not in the gating job. The healer is told to "do the most reasonable thing possible to pass the test", so a pass can mean a new locator, a looser assertion or a skip. A gating job that runs only committed tests and counts skips, behind a code owner's review, keeps its signal. Sort each heal diff (the edit that makes a failing test pass) as locator drift, timing or expectation change, each with one accept rule.
Table of contents
This post assumes:
What the three Test Agents are and where the model runs
Playwright Test Agents are three roles shipped in 1.56 (October 2025) and current in 1.64.1 (as of October 2026): a planner that writes a test plan, a generator that writes tests from it, and the healer, which per the docs "executes the test suite and automatically repairs failing tests". This post uses only the healer.
init-agents writes agent definitions (Markdown or TOML files with a role prompt, a tool list and sometimes a model: line) and registers an MCP (Model Context Protocol) server, a local process that exposes tools to an agent; here npx playwright run-test-mcp-server drives the browser and runs tests. Your agent tool (Claude Code here) supplies the model; Playwright ships none, and npx playwright test never heals anything.
Why the healer runs on a branch, not in the gating job
Run the healer on a branch, read its heal diff, and let the gate run only committed tests. The docs state the healer's output as "A passing test, or a skipped test if the healer believes that functionality is broken", and both leave the exit code at 0: a gate that runs the healer can turn itself green.
As of October 2026 the Test Agents docs say nothing about CI or where to run the healer, so the rule is Testland's, not Playwright's. It follows visual tests that pass for the right reasons: a check earns its CI minutes only when it passes without hiding the change it exists to catch, and a step that edits tests, then runs them, has no independent judge. The skip guard is built below.
| Where | What runs | Who judges |
|---|---|---|
| Your machine, on a branch | The healer, then the suite | You, reading git diff |
| Pull request, gating job | Committed tests only, no model | The exit code plus the skip guard |
| Pull request review | The diff to the five owned paths (the CODEOWNERS block below) | A code owner who did not run the healer |
Step 1: pin the Playwright version and run init-agents
Pin the exact version, then run init-agents with --loop=claude. --loop picks the agentic loop provider (the coding tool that runs the definitions); --help lists six values and the docs guide shows four (issue 43440).
# Playwright 1.64.1
npm install --save-dev --save-exact @playwright/test@1.64.1
npx playwright --version
npx playwright init-agents --loop=claude 🎭 Using project "" as a primary project
📝 specs/README.md - directory for test plans
🌱 tests/seed.spec.ts - default environment seed file
🤖 .claude/agents/playwright-test-generator.md - agent definition
🤖 .claude/agents/playwright-test-healer.md - agent definition
🤖 .claude/agents/playwright-test-planner.md - agent definition
🔧 .mcp.json - mcp configuration
✅ Done.{
"mcpServers": {
"playwright-test": {
"command": "npx",
"args": [
"playwright",
"run-test-mcp-server"
]
}
}
}The empty project name comes from the sample config, and the specs/README.md and seed lines appear on a first run only. The seed test (tests/seed.spec.ts) sets up the environment the agents use. The healer starts from a failing test, so specs/ and the seed stay untouched here. One docs trap: under "Example for Claude Code subagents" the docs source shows --loop=vscode; use --loop=claude.
Step 2: read what the healer is told and allowed to edit
Nothing in the healer's tool list restricts where its edits land, though its instructions say to "Edit the test code". Of its 16 tools, 3 write files (Edit, MultiEdit, Write), none path-restricted, and there is no Bash: tests run through MCP tools. model: sonnet is the Claude template's setting only.
# .claude/agents/playwright-test-healer.md (Playwright 1.64.1)
name: playwright-test-healer
description: Use this agent when you need to debug and fix failing Playwright tests
tools: Glob, Grep, Read, LS, Edit, MultiEdit, Write, mcp__playwright-test__browser_console_messages, mcp__playwright-test__browser_evaluate, mcp__playwright-test__browser_generate_locator, mcp__playwright-test__browser_network_request, mcp__playwright-test__browser_network_requests, mcp__playwright-test__browser_snapshot, mcp__playwright-test__test_debug, mcp__playwright-test__test_list, mcp__playwright-test__test_run
model: sonnet
color: redThe instructions loop until "the test runs successfully without any failures or errors"; the docs add that "guardrails" can stop the loop, a term they never define. The same lines name fixing assertions and expected values, regular expressions for "resilient locators", and test.fixme() (it marks a test known-broken and skips it) at "high level of confidence that the test is correct".
5. **Code Remediation**: Edit the test code to address identified issues, focusing on:
   - Updating selectors to match current application state
   - Fixing assertions and expected values
   - Improving test reliability and maintainability
   - For inherently dynamic data, utilize regular expressions to produce resilient locators
...
- You will continue this process until the test runs successfully without any failures or errors.
- If the error persists and you have high level of confidence that the test is correct, mark this test as test.fixme()
  so that it is skipped during the execution. Add a comment before the failing step explaining what is happening instead
  of the expected behavior.
- Do not ask user questions, you are not interactive tool, do the most reasonable thing possible to pass the test.
- Never wait for networkidle or use other discouraged or deprecated apisIn one single-run anecdote (azukiazusa, October 2025, translated), the healer's own summary lists an edit to application code (a CardTitle <div> changed to an <h3> in components/ui/card.tsx) and an await page.reload() added after await page.goto("/").
The instruction text is identical across all six loops; the subagent definition files differ:
| Loop | Healer file | Edit-capable entry |
|---|---|---|
| claude | .claude/agents/playwright-test-healer.md | Edit, MultiEdit, Write in tools: |
| codex | .codex/agents/playwright_test_healer.toml | sandbox_mode = "workspace-write" |
| copilot, vscode | .github/agents/playwright-test-healer.agent.md | edit (with search) in tools: |
| opencode | .opencode/prompts/playwright-test-healer.md, with the tools in opencode.json | "edit": true and "write": true in opencode.json |
Step 3: run the healer on a seeded failure
Seed one failure by renaming a class that one test's locator depends on, commit it, then branch and run the suite. The output is real; the run takes 30.0s (the default 30000ms test timeout).
git switch -c heal/checkout-locators
npx playwright test tests/checkout.spec.tsRunning 1 test using 1 worker
✘ 1 tests/checkout.spec.ts:3:5 › placing an order shows the confirmation and total (30.0s)
1) tests/checkout.spec.ts:3:5 › placing an order shows the confirmation and total ────────────────
Test timeout of 30000ms exceeded.
Error: locator.click: Test timeout of 30000ms exceeded.
Call log:
- waiting for locator('.btn-checkout')
3 | test('placing an order shows the confirmation and total', async ({ page }) => {
4 | await page.goto('/');
> 5 | await page.locator('.btn-checkout').click();
| ^
6 | await expect(page.getByRole('heading', { name: 'Order confirmed' })).toBeVisible();
7 | await expect(page.getByTestId('total')).toHaveText('$42.00');
8 | });
Error Context: test-results/checkout-placing-an-order-shows-the-confirmation-and-total/error-context.md
1 failed
tests/checkout.spec.ts:3:5 › placing an order shows the confirmation and total ─────────────────npx playwright test edits nothing, so git status stays clean while test-results/ is gitignored. Start claude in the repo root, then approve the project's playwright-test MCP server when prompted and invoke the healer by name with the failing test as input. The prompt below is unrun wording, not a transcript.
@agent-playwright-test-healer tests/checkout.spec.ts

Use the playwright-test-healer subagent to heal tests/checkout.spec.tsNo healer output is shown, because it depends on the model; Step 4's diffs are constructed illustrations built from the definition's instructions. After a run, check for changes outside tests/ and for added skips, then read every hunk; a new test file shows in the status check, not the diff, so open it.
# 1. Anything modified or added outside tests/ (a plain git diff would miss new files)
git status --short -- . ':(exclude)tests'

# 2. Any skip or fixme added to a test (prints nothing when clean)
git diff HEAD -U0 -- tests | grep -nE '^\+[^+].*\.(fixme|skip)\('

# 3. Which files under tests/ changed
git status --short -- tests

# 4. Every hunk of the heal diff
git diff HEAD -- testsStep 4: sort each heal diff into one of three buckets
The docs describe the healer as suggesting "a patch (e.g., locator update, wait adjustment, data fix)". Two buckets take the first two classes under the post's own names, locator drift and timing. Expectation change is Testland's bucket, not Playwright's: it collects every edit that alters what counts as correct, and it absorbs "data fix", which the docs list without defining.
Locator drift changes which element a step targets
Accept when a person confirms the new locator hits the same control (role, name, purpose) and repeat runs stay green; neither alone is enough. Reject broader regexes and positional picks that weren't there before.
Constructed illustration of the docs' locator update (the test then passes in about 0.5s):
--- a/tests/checkout.spec.ts
+++ b/tests/checkout.spec.ts
@@ -2,7 +2,7 @@ import { test, expect } from '@playwright/test';

 test('placing an order shows the confirmation and total', async ({ page }) => {
   await page.goto('/');
-  await page.locator('.btn-checkout').click();
+  await page.getByRole('button', { name: 'Place order' }).click();
   await expect(page.getByRole('heading', { name: 'Order confirmed' })).toBeVisible();
   await expect(page.getByTestId('total')).toHaveText('$42.00');
});In one single-run anecdote (Debbie O'Brien on dev.to, November 2025; no diff shown), a test looked for a textbox where the app now used a combobox, and the agent updated the locators: a role change no repeat run can flag, so only the diff read catches a wrong one.
Timing changes when a step acts or asserts
Accept a retrying assertion, optionally with a wait on a named response. Reject waitForTimeout, bigger timeouts and networkidle, which the definition says never to wait for. A person decides whether timing edits are sound (flaky-test guide).
Constructed illustrations of the docs' wait adjustment. The test reads the total once, before the API's 300ms response arrives. A fixed sleep:
--- a/tests/checkout.spec.ts
+++ b/tests/checkout.spec.ts
@@ -3,6 +3,7 @@ import { test, expect } from '@playwright/test';
 test('placing an order shows the confirmation and total', async ({ page }) => {
   await page.goto('/');
   await page.locator('.btn-checkout').click();
+  await page.waitForTimeout(3000);
   await expect(page.getByRole('heading', { name: 'Order confirmed' })).toBeVisible();
   expect(await page.getByTestId('total').textContent()).toBe('$42.00');
});The second illustration waits on the named response, then asserts with a retrying assertion:
--- a/tests/checkout.spec.ts
+++ b/tests/checkout.spec.ts
@@ -2,7 +2,9 @@ import { test, expect } from '@playwright/test';

 test('placing an order shows the confirmation and total', async ({ page }) => {
   await page.goto('/');
+  const totalLoaded = page.waitForResponse('**/api/total');
   await page.locator('.btn-checkout').click();
   await expect(page.getByRole('heading', { name: 'Order confirmed' })).toBeVisible();
-  expect(await page.getByTestId('total').textContent()).toBe('$42.00');
+  await totalLoaded;
+  await expect(page.getByTestId('total')).toHaveText('$42.00');
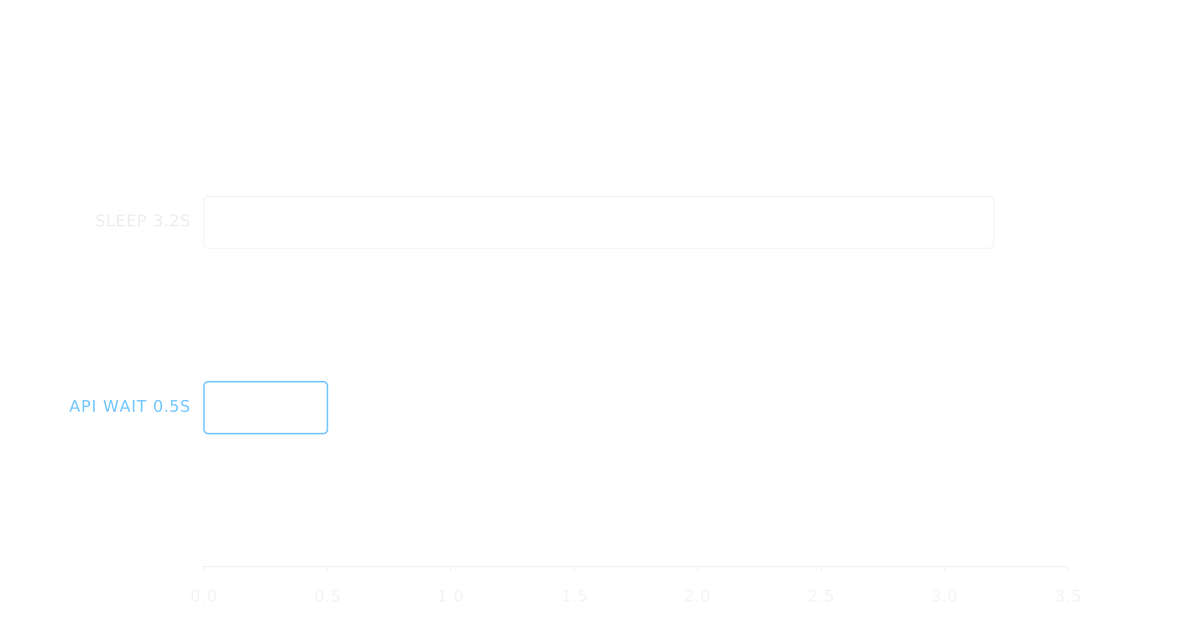
});The 3000ms sleep costs 3.2s per test against about 0.5s, and fails when the API takes 4000ms.
Expectation changes alter what counts as correct
Never auto-accept these. The person who owns the behavior decides between an intended change and a bug. The docs' "data fix" lands here: any edit to test data or an expected value changes what the test proves.
A loosened regex shows why green is not evidence. Constructed illustration:
--- a/tests/checkout.spec.ts
+++ b/tests/checkout.spec.ts
@@ -3,6 +3,6 @@ import { test, expect } from '@playwright/test';
 test('placing an order shows the confirmation and total', async ({ page }) => {
   await page.goto('/');
   await page.locator('.btn-checkout').click();
-  await expect(page.getByRole('heading', { name: 'Order confirmed' })).toBeVisible();
+  await expect(page.getByRole('heading', { name: /order/i })).toBeVisible();
   await expect(page.getByTestId('total')).toHaveText('$42.00');
});Against a build whose heading reads "Order failed", npx playwright test tests/checkout.spec.ts (output trimmed to the key lines, exit code appended) fails with the original assertion and passes with the loosened one:
  ✘  1 tests/checkout.spec.ts:3:5 › placing an order shows the confirmation and total (5.2s)
    Error: expect(locator).toBeVisible() failed
    Locator: getByRole('heading', { name: 'Order confirmed' })
    Expected: visible
    Timeout: 5000ms
    Error: element(s) not found
1 failed ✓ 1 tests/checkout.spec.ts:3:5 › placing an order shows the confirmation and total (489ms)
1 passed (1.3s)
exit code: 0In the O'Brien run, the agent "adjusted the regex to make the test more flexible" and marked a test test.fixme for a likely backend failure; only a diff read shows what the regex now accepts.
A test.fixme() is a bug report, not a heal. The definition names the no-argument form; the 1.64.1 package's API text advises test.fixme(title, body) instead, and the annotations page documents fixme for a test that is "slow or crashes". Require a linked ticket and an owner in the comment. Constructed illustration (the call sits at the top, so the whole test is skipped):
--- a/tests/checkout.spec.ts
+++ b/tests/checkout.spec.ts
@@ -1,6 +1,8 @@
 import { test, expect } from '@playwright/test';

 test('placing an order shows the confirmation and total', async ({ page }) => {
+  test.fixme();
+  // Heading reads "Order failed" after Place order, where the test expects "Order confirmed".
   await page.goto('/');
   await page.locator('.btn-checkout').click();
await expect(page.getByRole('heading', { name: 'Order confirmed' })).toBeVisible();Confirm a heal with repeat runs, then read the diff again
--repeat-each <N> runs each test N times; --fail-on-flaky-tests fails the run if any test is flagged flaky, meaning it passed only on a retry. The flag matters only when retries are configured (--retries defaults to none): on 1.64.1, a spec that fails only on its first attempt exits 0 with --retries=2 and 1 once the flag is added.
npx playwright test tests/checkout.spec.ts --repeat-each=10 --fail-on-flaky-tests; echo "exit code: $?"Running 10 tests using 2 workers
...
10 passed (6.2s)
exit code: 0Ten green runs show the heal is stable. They can't show that a locator hits the same element or that an assertion still checks the same thing; reading the diff is that check.
Fail the gating job when a heal leaves a skipped test
On Playwright 1.64.1, a run whose only outcome is a test.fixme() skip exits 0 while the JSON report shows skipped: 1. No option fails a run on skips: failOnFlakyTests and forbidOnly are the only options in the shipped types that turn a passing run into a failing one, and neither looks at skips. With the fixme illustration applied and the seed test beside it:
PLAYWRIGHT_JSON_OUTPUT_FILE=results.json npx playwright test --reporter=list,json; echo "exit code: $?"
jq -c '.stats | del(.startTime, .duration)' results.json
jq -e '.stats.skipped == 0' results.json; echo "guard exit code: $?"Running 2 tests using 2 workers
- 1 tests/checkout.spec.ts:3:5 › placing an order shows the confirmation and total
✓ 2 tests/seed.spec.ts:4:7 › Test group › seed (251ms)
1 skipped
1 passed (1.1s)
exit code: 0
{"expected":1,"skipped":1,"unexpected":0,"flaky":0}
false
guard exit code: 1The workflow below (.github/workflows/tests.yml) fails above a committed budget (0 here; a suite with legitimate skips sets its current count). It has no agent step, no model secret and a read-only token, and --fail-on-flaky-tests keeps a pass on retry from counting as green. With no model in it, the job stays deterministic.
The guard reads stats.skipped, a shape documented in the package's types/testReporter.d.ts, not on the reporters page; it also counts test.skip and test.describe.skip. The block below uses the current majors, v7 as of October 2026 (checkout, setup-node).
# Gating check for pull requests. No agent step, no model secret.
name: tests

on: pull_request

permissions:
  contents: read

jobs:
  e2e:
    runs-on: ubuntu-latest
    env:
      PLAYWRIGHT_JSON_OUTPUT_FILE: results.json
      # Skipped tests allowed in this suite. Raise it only in a reviewed change.
      SKIP_BUDGET: 0
    steps:
      - uses: actions/checkout@v7
      - uses: actions/setup-node@v7
        with:
          node-version: lts/*
          cache: npm
      - run: npm ci
      - run: npx playwright install --with-deps chromium
      # --fail-on-flaky-tests: a pass on retry is not green.
      - run: npx playwright test --reporter=list,json --fail-on-flaky-tests
      - name: Fail when the run skipped more tests than the budget
        run: |
          skipped=$(jq '.stats.skipped' results.json)
          echo "skipped tests: $skipped (budget: $SKIP_BUDGET)"
test "$skipped" -le "$SKIP_BUDGET"Keep the limits outside the files init-agents rewrites
A rerun of init-agents erases local edits
In all six loops, a line appended to the healer file is gone after init-agents runs again. With --loop=claude, a second server added to .mcp.json is gone too. The docs say definitions "should be regenerated whenever Playwright is updated", so following that step erases local edits to generated files, and an uncommitted edit leaves nothing in git status.
# Playwright 1.64.1; the generated files are committed
echo "- LOCAL RULE: only edit files under tests/." >> .claude/agents/playwright-test-healer.md
npx playwright init-agents --loop=claude
grep -c 'LOCAL RULE' .claude/agents/playwright-test-healer.md   # prints 0

jq '.mcpServers.other = {"command": "echo"}' .mcp.json > .mcp.tmp && mv .mcp.tmp .mcp.json
npx playwright init-agents --loop=claude
jq -c '.mcpServers | keys' .mcp.json # prints ["playwright-test"]Commit the generated files unmodified, so a rerun after an upgrade shows up in git diff.
Three places a rerun cannot reach
Claude Code permission rules, the gating workflow above and CODEOWNERS sit beyond a rerun's reach. A hand-made .claude/settings.json survived a rerun in every loop.
Write the fence as .claude/settings.json deny rules, which Claude Code evaluates first (permissions docs). "Edit rules apply to all built-in tools that edit files", so one Edit deny covers Write and MultiEdit. The sample has 6 entries (src/ and app/ are placeholders for your application directories; use your real config file name if it differs).
{
  "permissions": {
    "deny": [
      "Edit(src/**)",
      "Edit(app/**)",
      "Edit(playwright.config.ts)",
      "Edit(.github/**)",
      "Edit(.claude/**)",
      "Edit(.mcp.json)"
    ]
  }
}Test it once: ask the healer to edit a file under src/ and expect a refusal. The docs say a Bash deny rule applies to subagents and say nothing equivalent for an Edit deny on a custom project subagent; if the healer doesn't refuse, the fence isn't binding it.
Deny rules are the control in a non-interactive claude -p run in a never-trusted folder: the permissions page lists .mcp.json servers as "Connected without asking, approved or not", so no prompt appears. Other loops have their own permission or sandbox settings; Codex's sandbox_mode = "workspace-write" is not a tests-only fence.
With .github/CODEOWNERS and "Require review from Code Owners", the person who ran the healer is the pull request author and can't approve changes to the five owned paths (mechanics and the admin-bypass caveat). On other platforms, use a protected path plus a required reviewer.
# Changes to tests, agent definitions and CI need a review from the test reviewers.
/tests/                @your-org/test-reviewers
/.claude/              @your-org/test-reviewers
/.mcp.json             @your-org/test-reviewers
/.github/              @your-org/test-reviewers
/playwright.config.ts @your-org/test-reviewersWhat to do after a Playwright upgrade
After each upgrade, rerun init-agents and read the git diff on .claude/ and .mcp.json as the review of what the new version tells the healer. From 1.63.0 to 1.64.1, the healer definition came back byte-identical. Learn more in the Playwright Test Agents docs.